Things to know before implementation: the accuracy of Japanese speech recognition
When comparing speech recognition services, many people are primarily concerned with "how accurately they can recognize Japanese." However, the meaning of "accuracy" is far more complex than one might think. This article delves into why Japanese is difficult to recognize and how AmiVoice addresses this challenge, focusing on the "accuracy of Japanese."
Things you can't tell just from "accuracy of X%"
Many people are initially concerned with the percentage of recognition accuracy. While this is certainly an important indicator, focusing solely on this number can lead to disappointment when actually using the device, as it may not meet expectations.
One of the causes is the issue of "which word was mistaken."
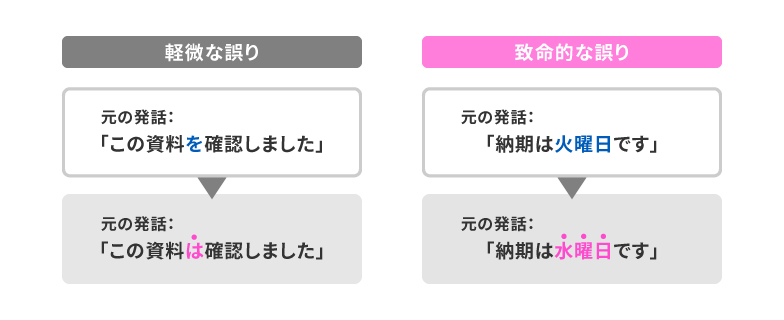
For example, compare the following two misconceptions.
- The recognition system mistakenly recognized "この資料を確認しました" (I have reviewed this document) as "この資料は確認しました" (This document has been confirmed).
- The recognition system mistakenly recognized "納期は火曜日です" (The deadline is Tuesday) as "納期は水曜日です" (The deadline is Wednesday).
In typical error rate calculations (CER/WER), these two are treated as the same "single error." However, in actual business operations, the latter, which results in a loss of meaning, is overwhelmingly more critical. This difference becomes more pronounced in situations where recognition results are used in the "next process," such as creating meeting minutes, entering medical records, or summarizing and post-processing using AI.
In fact, verification conducted under the premise of post-processing by generative AI has demonstrated that improving the recognition accuracy of proper nouns and technical terms, rather than reducing the overall error rate, is directly linked to the quality of the final output. For detailed verification results, please refer to our blog post titled "What impact will speech recognition have on generative AI? New standards for quality evaluation.".
In other words, what we should really be looking at with Japanese speech recognition is not the "overall accuracy," but rather "how accurately it can pick up the words that determine the meaning."
Why is speech recognition so difficult in the first place?
Compared to alphabetic languages such as English, Japanese has several characteristics that make it unsuitable for speech recognition.
- There are a great many homophones (such as "機械 (machine)", "機会 (opportunity), and "奇怪 (strange)", which cannot be distinguished by sound alone).
- Word breaks are not clear (because there is no spacing between words, it is difficult to determine where to separate them).
- There is a lot of variation in spoken language (omission of sentence endings, fillers, dialects, industry-specific expressions).
- Proper nouns and technical terms continue to increase endlessly (personal names, place names, product names, company jargon, drug names, etc.)
The last category, "proper nouns and technical terms," in particular, is an area that cannot be adequately addressed with general-purpose training data alone. No matter how high-performance the engine, words it hasn't learned will basically be treated as "unknown words." The attention to punctuation and nuances of spoken language, which is introduced in "AmiVoice's Features," has been refined through confronting these unique difficulties of the Japanese language.
Why AmiVoice is strong in Japanese
1. Proper nouns and technical terms can be "registered".
The AmiVoice API's hybrid engine and end-to-end engine each have word registration and keyword boosting functions. By pre-registering business-specific words such as company names, product names, department names, and technical terms, the system can recognize those words with high accuracy. A key feature is that it only requires simple settings of "Written from (notation)" and "Spoken form (pronunciation)", allowing for later adjustment of recognition accuracy for each organization, regardless of whether the words are included in the training data. (For details, please see "About Word Registration" on the features page).
2. We offer industry-specific engines.
In addition to general-purpose engines, we offer a lineup of engines specialized for industry-specific terminology and phrasing in fields such as healthcare, finance, and insurance. For example, our medical engine is optimized for disease names, drug names, and surgical procedure names, and has been adopted by over 19,000 medical facilities. The ability to select language models optimized for each field is one of AmiVoice's key features.
3. Designed with AI integration in mind, making it "strong in downstream processes."
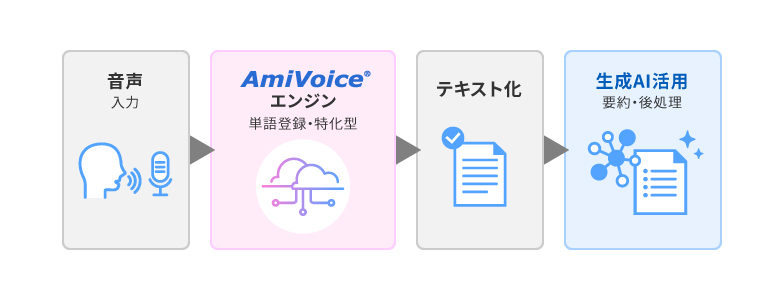
AmiVoice's recognition results are increasingly being used not only for "reading directly" but also for "passing on to the next AI or system," such as for automatically generating and summarizing meeting minutes and reflecting them in electronic medical records. As mentioned in the verification article above, the quality of subsequent processes largely depends on the accuracy of proper nouns. For about 30 years, AmiVoice has been working on Japanese speech recognition, and has refined its engine with an emphasis on "accurately picking up meaningful words."
4. Can output in an easy-to-read format.
The AmiVoice API automatically adds punctuation and question marks, and automatically removes fillers like "えー (um)" and "あのー (uh)" from the recognition results. Preparing the text in a format that is easy for humans to read or pass on to generative AI is crucial for quality in real-world applications. Note that with the hybrid engine, you can also choose to retain fillers in the results through configuration.
Summary
When implementing Japanese speech recognition, we recommend checking not only the overall accuracy percentage, but also the following points.
- Can we register and add our company's unique proper nouns and technical terms?
- Are there options available to suit specific applications, such as industry-specific engines?
- When combined with subsequent processes such as generative AI, will meaningful results be obtained?
These perspectives are important not only for determining the recognition accuracy of test data, but also for assessing whether high quality can be consistently maintained in a real-world work environment.
Another subtle but significant factor is the cost structure. AmiVoice only charges for spoken portions, with no charges for silent portions. Other companies' engines sometimes charge for the entire recording time, including silent portions, and this difference directly impacts costs, especially for audio recordings with many pauses and silences, such as meetings, medical consultations, and call centers.
The quickest method to understand these differences is to actually try them out. AmiVoice allows you to try all engines free of charge for up to 60 minutes per month. You can verify both accuracy and cost considerations at no expense using your company's proprietary terms, technical terminology, and actual conversation tones. Please try AmiVoice. To register for the AmiVoice API, please proceed from here.
If you have any questions regarding the AmiVoice API or SDK during implementation, please apply for an individual consultation session. Our staff will respond to your inquiries online.
Related article
Person who wrote this article
-
Unagiko
My first encounter with speech recognition was with Seaman. I like trying different kinds of food from different countries.
Most Viewed Articles
-
A quick explanation of how speech recognition works!
-
Comparing the speech recognition rates of OpenAI's Whisper and AmiVoice for "conference" audio
-
How to use the AmiVoice API free coupon
New Articles
-
How to Choose a Speech Recognition API: 4 Comparison Points to Avoid Mistakes
-
Things to know before implementation: the accuracy of Japanese speech recognition
-
Thank you for all your submissions! Here's a summary of Zennfes Spring 2026.
Category List
- Tech (1)
- Introduction to Speech Recognition (16)
- How to Improve Speech Recognition Accuracy (12)
- Tried Building It (27)
- How to Use AmiVoice API (28)
- Comparison and Verification (7)
- Others (10)
Archive