AmiVoice API Update: End-to-End "Keyword Biasing" Feature
AmiVoice API now supports user dictionary registration2 in its End-to-End ASR models1.
In this article, we provide an overview of the feature and explain how to use it.
User dictionary registration has been well received, but until now it was only available for hybrid speech recognition. User dictionary registration for end-to-end speech recognition poses technical hurdles, and is generally less effective than user dictionary registration for hybrid speech recognition. We will also explain the technical innovations that AmiVoice has made to improve this point.
End-to-end speech recognition is a powerful option when dealing with general-purpose vocabularies.
TL;DR
- In End-to-End speech recognition, the feature for registering words you want to appear in recognition results is called “keyword biasing.”
- Although the operating principle and detailed behavior are different, it can be used for the same purpose as "word registration" in hybrid speech recognition.
- It can be used by registering only the Written.
- There is no concept of class
- The biasing level can be adjusted on a per‑word basis.
Table of contents
- TL;DR
- Table of contents
- Overview
- How does word registration differ between hybrid ASR and End‑to‑End ASR?
- How to Use
- Written
- Alternative written
- Biasing level
- Tips
- Specifying the spoken for Alternative written
- Set the biasing level
- Register frequently misrecognized variants as Alternative writtens
- Do not assign desired output words as alternative writtens.
- Do not assign multiple Written forms to the same Alternative written.
- Do not assign different biasing levels to the same Written form.
- What should you do when classes cannot be used?
- Do not register words that are too short or have homonyms
- Avoid registering an excessive number of entries.
- So which approach performs better: End‑to‑End ASR or hybrid ASR?
- Reference
Overview
The word registration function used in conventional hybrid speech recognition is not possible with end-to-end speech recognition due to its structure.
Therefore, research and development into alternative functions using different methods is being actively carried out.
Advanced Media has also developed and is currently providing this technology. We refer to this feature as “keyword biasing” to distinguish it from word registration in hybrid ASR.
How does word registration differ between hybrid ASR and End‑to‑End ASR?
If you look only at the purpose of “registering words to make them more likely to appear in recognition results,” it can be considered the same. On MyPage, it is also listed as a user dictionary registration in the same category as word registration. However, since the mechanisms are different, the usage is different.
To put it very simply, E2E speech recognition is a black box, so there are fewer types of information that can be used to influence score calculation.
Details
Let's take a closer look at what this means (it gets a little technical).
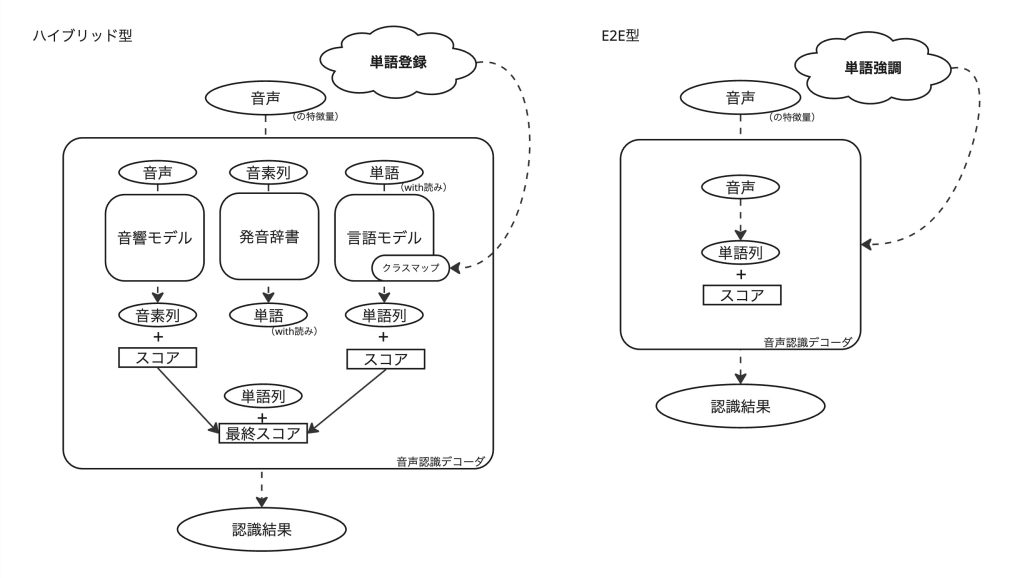
In speech recognition, the likelihood of multiple candidates is scored and compared to determine the final output, but both hybrid and E2E types intervene and upwardly revise the scores of candidates that contain registered words.
However, unlike the E2E type, the hybrid type scores using a collaboration of several modules. For example, the acoustic model + pronunciation dictionary that estimates the spoken and written of words from speech and the language model that estimates the validity of the word order are separate modules. For this reason, there is a phase in the processing pipeline where spoken information is explicitly handled, and the spokens registered by the user can be used to influence the score calculation. Also, like AmiVoice, the language model has classes.3 If you train the system, you can calculate scores that take into account the classes the user has registered.
On the other hand, E2E types are like all-in-one appliances that directly return text strings from voice input. They are not designed to explicitly handle information such as spokens or classes, so you cannot use such information to influence score calculation.
This lack of opportunity to intervene can be a hurdle.
In the E2E type, a simple implementation that directly adds a bias to the scores of candidates that contain the specified string is common, and this is also the case with AmiVoice. As a result, it is easy for cases to occur where a word that has been carefully registered is not even considered as a candidate and is ineffective. In particular, because there is no abstraction through classes, the word needs to appear as a candidate exactly as written. As will be explained later, a new setting value has been prepared to address this issue.
Additionally, research and development is underway on an improved version that addresses these weaknesses, and this will be available soon.
Although this has been a rather abbreviated explanation,
For those who are interested, please refer to other articles that explain the word registration mechanism and the differences between the Hybrid and E2E models.
How to Use
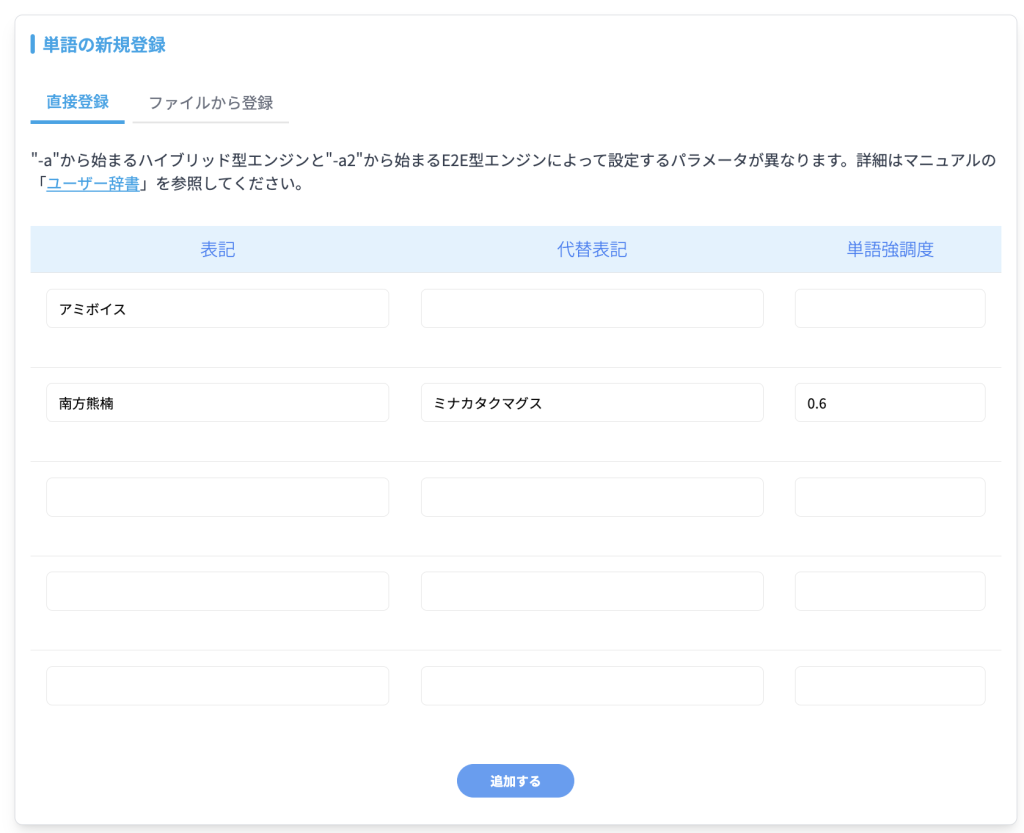
You can assign three items: “Written”, “Alternative written”, and “Biasing level”.
The only required parameter is the Written, and you can use it by simply setting the Written form of the word you want to appear in the results. For Japanese, we recommend registering the spoken in katakana as an Alternative written.
Written
Specify a written form for the word to appear in the recognition results. This is the same as the word registration feature in Hybrid Speech Recognition.
Alternative written
You can specify a string with a pronunciation similar to the string you want to recognize here, and replace it with the desired written form in the output. This is an optional item.
This is especially effective for foreign words and proper nouns. In the case of Japanese, it is effective to specify the spoken as described below.
Note that, as described in the notes below, any string specified as an Alternative written will also be biased (boosted). If this produces unintended behavior, consider adjusting the biasing level accordingly.
Supplemental
This is probably the parameter that most people are confused about.
If the string specified here is included in the recognition result candidates, the following two things will happen, which is why the above works.
- Increase the score of candidates that contain this string, similar to how 'Written' works
- This string is replaced with the 'Written' value
As mentioned in the explanation of how it works, keyword biasing will not work if the word was not originally considered as a candidate for recognition results. It is easier to understand if you think of it as a function to help with that.
Even if the character string registered in the Written is not one of the candidates, if there is another similar character string, you can pick it up, replace it with the 'Written' value and output it. Whereas using only 'Written' restricts you to a single target string, 'Alternative written' increases the number of possible variants that can be recognized and then normalized to the desired output.
Biasing level
Specify a numerical value that controls the strength of the bias applied to the speech recognition score. You can set a value between 0 and 1, and the higher the value, the more likely the word will appear in the recognition results. This setting is for each Written, and applies to any associated Alternative writtens. This is an optional item.
If you are unsure, you can leave it blank. If left blank, it will be treated as 0.5.
A value of 0 means no biasing.
A value of 1 is the maximum, but it does not guarantee 100% recognition. Instead, it applies a reasonably strong bias within a range that avoids unnatural recognition results.
Tips
Set the spoken for an Alternative written
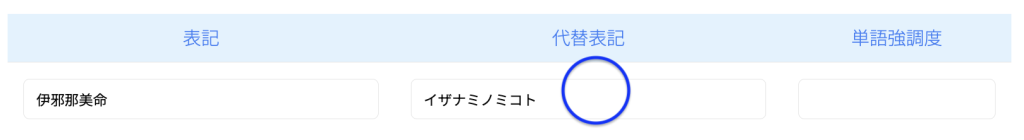
In the case of Japanese, specifying the spoken here will make it easier to recognize uncommon words and coined words. Katakana is more effective, so we recommend using katakana.
(Originally, this was an item for setting "character strings that are close in pronunciation to the character string you want to recognize," rather than spoken, but katakana written form also falls under this category, so it can be used in this way.)
Example:
Set the biasing level
If the registered word appears in unintended places, try lowering it; if the registered word rarely appears, try raising it.
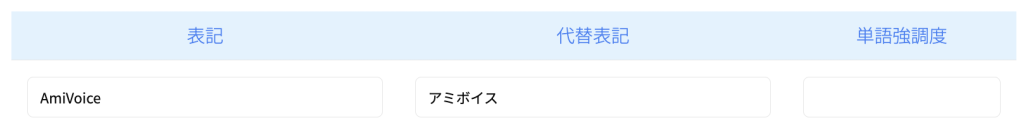
Configure words that are repeatedly misrecognized as an Alternative written.
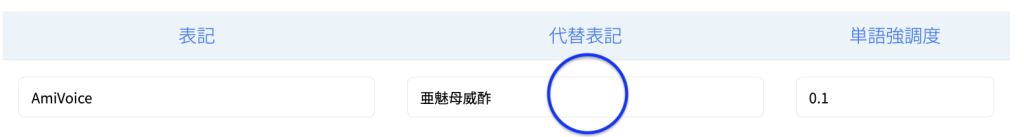
If you register the spoken as an Alternative written and adjust the biasing level, but it does not appear in the recognition results, it is possible that the Written and the Spoken are not being considered as candidates for the recognition results, and the keyword biasing is not working. In particular, if the same misrecognition occurs repeatedly, you can expect the keyword biasing to work by setting the string as an Alternative written instead.
When using this method, you can reduce the side effects by setting the keyword biasing to a low level.
Example:
For example, let's say you register the word "アミボイス" but it isn't recognized and is instead misrecognized as "亜魅母威酢." In this case, you would register "亜魅母威酢" as an alternative written.
↓
Do not assign desired output words as alternative writtens.
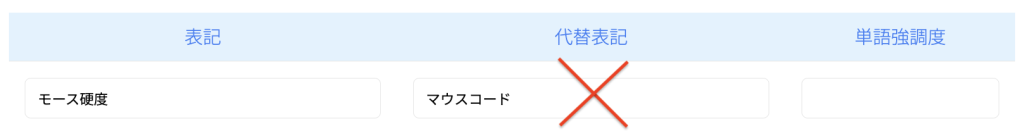
Since Alternative writtens are replaced by Writtens, strings specified as Alternative writtens will generally not appear in the recognition results (replacement occurs regardless of keyword biasing). Therefore, do not specify strings that you might want to appear depending on the context.
Bad example:
For example, if "モース硬度" is incorrectly recognized as "マウスコード," and you have set "マウスコード" as the Alternative written, even if you actually say "マウスコード," it will be recognized as "モース硬度."
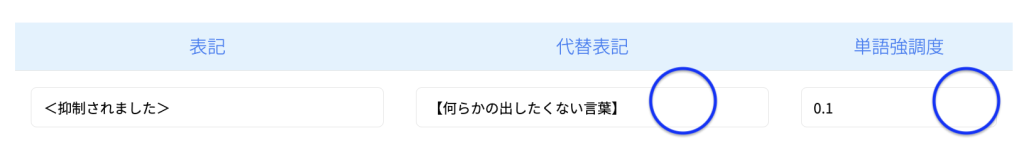
Conversely, you can also use this to suppress words you don't want to appear. In this case, you only want to perform replacement, so it's a good idea to set the biasing level to a low value so that the words you don't want to appear aren't overboosted. However, this doesn't mean that they will not appear 100%.
Example:
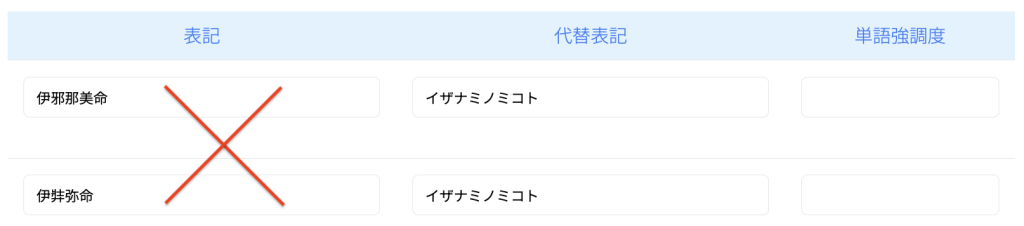
Do not assign multiple Written forms to the same Alternative written.
If such a registration exists, it will be unclear which written form an alternative written form should be mapped to. In actual operation, only one Written will be valid, but it is best to avoid this as it will make the behavior difficult to predict.
Bad example:
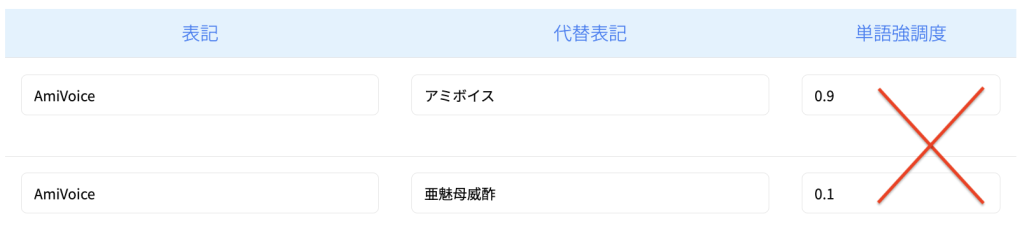
Do not assign different biasing levels to the same Written form.
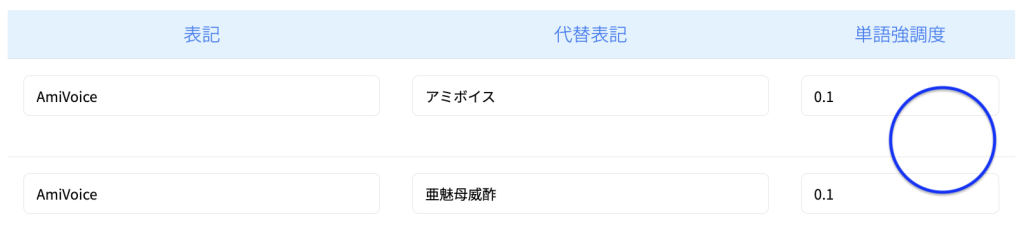
The data structure is such that the Written is the basic unit of registration, with the biasing level and multiple Alternative writtens corresponding to it. For API and UI reasons, even if the Written is the same, each Alternative written is registered separately, but if different biasing levels are specified for each Alternative written, only one value will be used.
Bad example:
Good example:
What should you do when classes cannot be used?
There is no corresponding function. In other words, the idea is that you don't have to do anything, and leave all the context and other decisions to the speech recognition decoder.
Do not register words that are too short or have homonyms
This is the same as with the hybrid model.
For example, if you specify “はし” as an Alternative written and “橋” as the Written form, “橋” may also appear in cases where the intended word is “端”, “箸”, or “走る”.
Avoid registering an excessive number of entries.
This is similar to the hybrid approach: aim for 1,000 words or less to start with, and aim for a maximum of a few thousand words.
So, which is better: Hybrid or End-to-End?
If your use case involves many technical terms or proper nouns, or if you want to use classes, please consider the hybrid engine mode.
Reference
- Keyword biasing official documentation
- Differences and features between hybrid speech recognition and End-to-End speech recognition
- Tips for registering words
- For details on the differences in specifications between the hybrid and end-to-end types, please click here.
https://docs.amivoice.com/en/amivoice-api/manual/engines/#difference-between-end-to-end-and-hybrid ↩︎ - With this release, we have changed the general term for these features to "User Dictionary Registration." The Hybrid "Word Registration" and E2E "Keyword Biasing" are collectively referred to as "User Dictionary Registration." ↩︎
- This refers to abstraction based on word types, such as people's names and place names.
https://acp.amivoice.com/blog/2022-01-13-101135/#%E5%8D%98%E8%AA%9E%E7%99%BB%E9%8C%B2%E3%81%AE%E3%82%AF%E3%83%A9%E3%82%B9%E3%81%A8%E3%81%AF ↩︎
Person who wrote this article
-
Mikiyasu Kobayashi
I am developing an application.
My interest in animal vocal communication led me to choose a speech recognition company.
I like observing nature, traveling, puzzles, games, etc. I feel like ChatGPT has become the person I chat with the most in my life.
Most Viewed Articles
-
A quick explanation of how speech recognition works!
-
Comparing the speech recognition rates of OpenAI's Whisper and AmiVoice for "conference" audio
-
How to use the AmiVoice API free coupon
New Articles
-
Organizing the AmiVoice API manual for AI generation - Providing Markdown and llms.txt files -
-
How to Choose a Speech Recognition API: 4 Comparison Points to Avoid Mistakes
-
Things to know before implementation: the accuracy of Japanese speech recognition
Category List
- Tech (1)
- Introduction to Speech Recognition (16)
- How to Improve Speech Recognition Accuracy (12)
- Tried Building It (27)
- How to Use AmiVoice API (29)
- Comparison and Verification (8)
- Others (10)
Archive