Prerequisites for developing systems using speech recognition <Part 1> - Development Know-how Series 1 -
Hello everyone.
When developing a speech recognition system, you may be worried about the accuracy of your speech recognition service.
Have you ever wondered, "Is there any way to control the system so that users can use speech recognition effectively?"
This time, we will be explaining in a series about useful knowledge to know before developing speech recognition.
The first installment will be a two-part detailed explanation of the "prerequisites for speech recognition."
This article is a compilation of content discussed in a previous webinar.
You can also watch the video below.
▶ [Video] [For Developers] This is the one thing you need to know! System development know-how for implementing speech recognition without failure (1) - Requirements definition and UI/UX edition -
Prerequisites for Speech Recognition (Part 1)
1. Why use speech recognition?
When using speech recognition, you need to carefully consider whether it is really a good idea to use it. First, let's understand the advantages and disadvantages of speech recognition.
| Advantages of speech recognition | Disadvantages of speech recognition |
|---|---|
| For long texts, it's faster than typing. | There may be misrecognition |
| I just need a microphone | Requires a microphone |
| No need to use your hands | It can be heard around |
| It can be transcribed more cheaply than by hand | It requires a lot of calculations (it requires a lot of CPU load and server fees) |
Keyboards, mice, touch panels, etc. are often superior to speech recognition as input methods. Also, for security and compliance reasons, if someone were to overhear something, it would be problematic, so it can only be used when no one is around, so it is limited. On the other hand, speech recognition can be more convenient under certain conditions.
<Examples when speech recognition is effective>
- When the input device is limited to a microphone only (such as a telephone)
- When there are a huge number of options (such as searching for a movie title)
- When you want to quickly transcribe long sentences (such as voice input for emails)
- When you want to transcribe large amounts of text more cheaply than manually (such as transcribing calls or meetings)
- When you want to input or operate without using your hands (such as recording warehouse work)
With all of this in mind, let's consider whether you should really use speech recognition.
2. What content will be recognized by voice?
Next, let's talk about the content you want to recognize by voice. Speech recognition cannot recognize anything you say, and the difficulty level varies depending on the content.
If the content you want to recognize by voice is difficult, the speech recognition may not perform to its full potential and the service may not be viable, so it is important to check in advance.
<List of difficult speech recognition tasks>
- The wider the topics covered and the more vocabulary there is, the more difficult it becomes.
The topic is broad → the number of unknown words increases → speech recognition engine cannot recognize the topic - The difficulty level increases when there are many words and phrases with similar spoken forms.
It is easy to mishear things that sound similar. For example, the alphabet and names are very difficult to pronounce. - Many speech recognition engines only cover general content
Measures are needed to accurately recognize uncommon content (technical terms, proper nouns, new words, etc.) - If you want to support multiple languages, you need language identification.
For example, you can select several words using a touch panel, and there are engines that can identify them from voice (OpenAI Whisper, etc.).
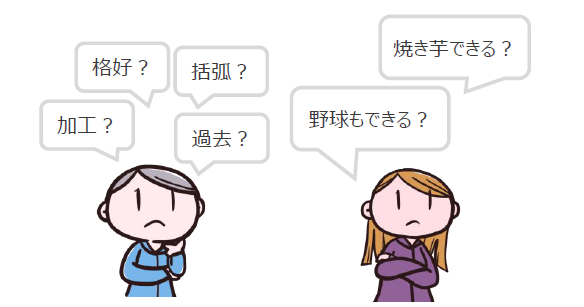
Words with similar spoken forms, such as "過去", "かっこ", and "加工", as shown in the illustration, are difficult to recognize during conversation. Synonyms cannot be determined based on sound alone, and the context in which they were spoken must be determined.
3. Recognition range of the speech recognition engine
The coverage area of the speech recognition engine is shown in the diagram below.
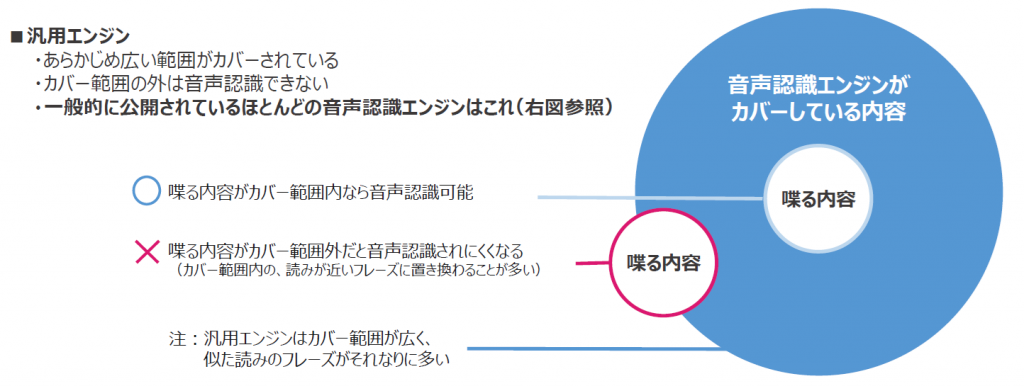
The blue circle in the diagram represents the range that speech recognition can cover. Content within the coverage range mainly refers to general everyday conversation. However, if the conversation contains technical terms or unique words, the range will partially fall outside the range, as shown by the red circle in the diagram. This may result in speech not being recognized or in the wrong words being recognized.
When you want to perform speech recognition on the protruding portions of this red circle, it is necessary to register words or perform additional training. Word registration refers to registering a word by specifying its written form and spoken form, while additional training refers to having the speech recognition engine learn sentences.
It is important to note here that the general-purpose engine is originally registered with a wide range of Japanese words and vocabulary, so if you register more words or perform additional training, there is a possibility that it may mistakenly identify similar phrases or words with the same spoken form.
To resolve such recognition errors, there is a method to intentionally limit the coverage area.
To explain in more detail, this method recognizes only the necessary words and phrases, and does not register words in the engine that do not need to be recognized. Highly accurate speech recognition is possible when the purpose of the speech recognition system and the content of the speech you want to recognize are decided.
<In the case of AmiVoice>
We provide speech recognition engines with additional training and limited coverage.
- Domain-specific engine: Engines specialized in specific fields (e.g., medical), and engines that use general vocabulary and technical terms from various industries (e.g., finance, insurance)
- Custom-built engine: A unique engine built from a large amount of text
- Rule grammar: Developer defines the grammar
Please contact us for individual construction engines and rule grammars.
4. The difficulty of speech recognition varies depending on the words and phrases being recognized.
So far, we have explained that there are conversations and words that are difficult for speech recognition to recognize. We have summarized some concrete examples in the table below for your reference.
| Relatively difficult | Relatively easy | Reason/Notes |
|---|---|---|
| The alphabet | Numerals | There are many alphabets that sound similar. ・Numbers have few similar spoken forms, with some exceptions such as "いち" and "しち". |
| Unspecified apartment/condominium/building/store name | Landmark Name | ・There are many unique or unknown names of apartments and condominiums. This requires the use and customization of a dedicated speech recognition engine. ・Landmark names are more constrained. This can be covered by word registration etc. |
| Unspecified name | Celebrity names | ・There are many unspecified names that sound similar. This requires the use and customization of a dedicated speech recognition engine. ・Names of famous people are more constrained. This can be covered by registering words, etc. |
| electronic medical records | Radiology reading report | ・Interpreting radiographs is very specialized and may seem difficult at first glance, but the range of words and phrases that appear is not that wide. Electronic medical records contain unique elements, such as the reason for an injury, and the range of content is wide, making it more difficult. ・Both require the use and customization of a dedicated speech recognition engine |
| Non-standard conversations (daily conversations, etc.) | Standard conversations (reception work, etc.) | ・Standard conversations have limited words and phrases, making them less difficult ・Daily conversations are more difficult because they contain a variety of words and phrases. ・Both can be covered to some extent by the default speech recognition engine |
5. What should I do if I want to recognize difficult content?
We have mentioned that there are conversations that are difficult for speech recognition to analyze, but if you still want to recognize difficult content, we will explain what measures you can take.
As a premise, 100% accurate speech recognition is not realistic with current technology. It is important to recognize that speech recognition is inherently uncertain, and that a certain degree of misrecognition is unavoidable. With that in mind, we will consider the following countermeasures.
- Avoiding difficult words
Since names are difficult to distinguish, use user IDs. Alphabet characters in user IDs are also difficult to distinguish, so use only numbers. Since unspecified names are difficult, if they can be specified in advance, use speech recognition from among those candidates. - Prepare a mechanism to recover from misrecognition
Show the results to the user and encourage them to repeat or correct their mistakes - Use it in a way that tolerates misrecognition
Create a workflow for later human confirmation. Validate input data. Use it for statistical analysis.
Knowing these things will be useful when you want to recognize difficult content through speech recognition.
Prerequisites for Speech Recognition Summary of Part 1
In this article, we explained the prerequisites for speech recognition, including the advantages and disadvantages of speech recognition, the difficulty of recognizing certain content, and the range of speech recognition engines available. Understanding these points before considering adopting a speech recognition engine will serve as a basis for selecting and developing a speech recognition engine that is right for your company.
Next time, we will explain the second part of the prerequisites for speech recognition.
Most Viewed Articles
-
A quick explanation of how speech recognition works!
-
Comparing the speech recognition rates of OpenAI's Whisper and AmiVoice for "conference" audio
-
How to use the AmiVoice API free coupon
New Articles
-
Organizing the AmiVoice API manual for AI generation - Providing Markdown and llms.txt files -
-
How to Choose a Speech Recognition API: 4 Comparison Points to Avoid Mistakes
-
Things to know before implementation: the accuracy of Japanese speech recognition
Category List
- Tech (1)
- Introduction to Speech Recognition (16)
- How to Improve Speech Recognition Accuracy (12)
- Tried Building It (27)
- How to Use AmiVoice API (29)
- Comparison and Verification (8)
- Others (10)
Archive