Prerequisites for developing systems using speech recognition <Part 2> - Development Know-how Series 2 -
Hello everyone.
This series explains useful information to know before implementing speech recognition from the perspective of a speech recognition system developer. This time, we will cover "Prerequisites for Speech Recognition: Part 2."
This article is a compilation of content discussed in a previous webinar.
You can also watch the video below.
▶ [Video] [For Developers] This is the one thing you need to know! System development know-how for implementing speech recognition without failure (1) - Requirements definition and UI/UX edition -
Prerequisites for Speech Recognition (Part 2)
1. In what situations should speech recognition be performed?
Last time, we explained the advantages and disadvantages of speech recognition, the difficulty of recognizing certain content, and the range of speech recognition engines available. In the second half, we will start by explaining situations and speaking styles that are easy to recognize.
First, I'll introduce the less difficult ones.
First, there are "Dictation" and "Voice Commands", which allow operation by voice instead of using a keyboard.
A familiar example would be voice input on a smartphone (OK Google, Hey Siri, etc.). Because the purpose is to input text and perform operations, even if there is a malfunction or misrecognition, the user can simply repeat the speech in a way that is easier to understand, so the difficulty of speech recognition is relatively low.
Next, as a scene with a medium difficulty level, "Voice Dialogue System" can be cited.
When people talk to machines, many users naturally speak in a way that is easy to understand, so the difficulty of speech recognition tends to be low. However, with recent advances in technology, voice dialogue systems are able to converse as smoothly as humans, which has led to users speaking in a slightly more casual manner, making it harder for the system to understand, and making speech recognition more difficult.
Furthermore, the most difficult scenario is "Conversation (such as meetings or calls)".
People who are speaking in meetings or on the phone are often unaware that their speech is being recognized, so they tend to speak in a casual manner that is just barely understandable to the other person. This makes it more difficult.
To address differences in speaking styles, AmiVoice API provides and supports different types of engines according to the usage scenarios (speaking styles). For example, two types of "acoustic models," which are engines that analyze sound, are provided: one "for conversation" and one "for voice input".
2. Availability of external services
Next, the accuracy of speech recognition is also affected by whether or not external services can be used.
There are also cases where you may want to use speech recognition in an environment where the Internet is not available or where voice cannot be sent externally for security reasons.
<When external services are available>
You can use speech recognition APIs published on the Internet.
・Many manufacturers have released speech recognition APIs, and all of these can be used
・While it is easy to use, it is often difficult to make detailed settings or adjustments
・Unavailable when a failure occurs
・Security precautions may be required
First, regarding the case where external services that can be used via the Internet are available, I believe that most speech recognition engines in the world are provided via APIs on the Internet.
If you have access to the internet, you have a wider selection of speech recognition engines to choose from, and many of them are easy to use. On the other hand, you cannot make detailed settings or customize the speech recognition engine.
When external services cannot be accessed, or an isolated internal environment is required (e.g. for internal meetings), you need to deploy a server within the local network.
<When external services cannot be used (internal environment construction)>
Build a server on your local network (on-premise or private cloud)
・Available speech recognition engine manufacturers are limited
・This deployment mode supports fine-grained configuration and custom training of proprietary speech recognition engines
・When a problem occurs, you must deal with it yourself
・You can freely adjust the security level, but at your own risk
On-device speech recognition
・Available speech recognition engine manufacturers are even more limited
・It may not be usable depending on the OS and specifications of the device
When using a speech recognition engine on a local network, it is necessary to create an internal server environment, which can lead to the issue of having to deal with problems in-house.
Although the types of speech recognition engines that can be used on a local network are limited, they allow for detailed configuration and customization.
There is also a method to use speech recognition within the device, such as a smartphone or PC. However, the engines and devices that can be used are quite limited.
3. Real-time Performance
We have covered the prerequisites for speech recognition engines, and this is the last condition: real-time performance.
Many speech recognition engines have two types of interfaces: "streaming" and "file." *This may differ depending on the manufacturer.
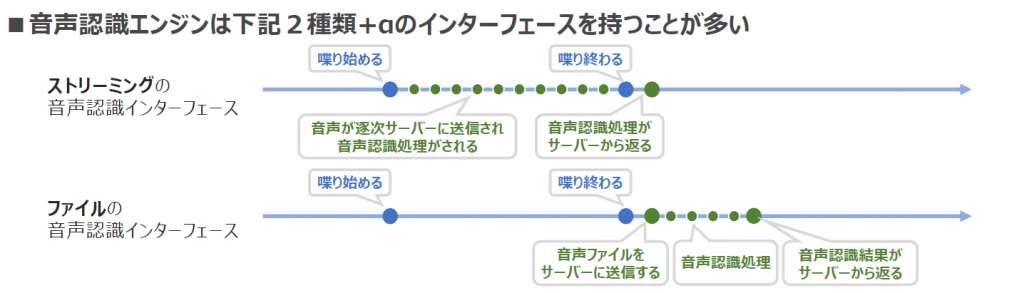
We will explain the features of each with reference to the diagram above.
With streaming, the audio you speak is sent to the server as soon as you start speaking, and speech recognition continues even while you're speaking. This means you can see the progress of the speech recognition results even while you're speaking. The speech recognition process is complete the moment you stop speaking, so you can see the results immediately.
The file is only recorded from the start to the end of speaking and is not sent to the server. Instead, once you finish speaking and the audio data is saved to a file, the data is sent to the server for speech recognition. Therefore, it takes a little time from the time you finish speaking until you can check the speech recognition results.
| Interface | Characteristics | Typical Uses |
|---|---|---|
| Streaming | ・Because it is sequential processing, it is highly real-time, and the speech recognition results are usually obtained quickly after you finish speaking. ・Intermediate progress of speech recognition may be obtained ・A little difficult to implement ・Streaming is better if you need a fast response time | ・Voice commands ・Speech translation ・Text input by voice ・Voice dialogue system |
| File | ・Speech recognition processing starts after you finish speaking, so real-time performance is poor ・It is possible to take more time for speech recognition processing than with streaming, which may result in higher accuracy →AmiVoice API's "asynchronous HTTP interface" is more accurate than others ・If response speed is not required, files are better | ・Analysis of meeting and call content |
Files are less real-time, but they allow more processing time for speech recognition. Depending on the manufacturer, speech recognition accuracy can be improved compared to streaming. In fact, AmiVoice has been adjusted so that speech recognition is slightly better with files.
For applications where response speed is not required, such as analysis, files are more suitable.
Summary of prerequisites for speech recognition
This article has been divided into two parts and explains the prerequisites for speech recognition. It provides basic knowledge about speech recognition engines that will be useful when considering the implementation of a speech recognition system.
Just as the challenges faced by different companies, occupations, and workplaces vary, the ability to maximize the use of speech recognition systems also differs depending on the situation. We hope that the prerequisites explained here will be useful when selecting and considering the implementation of a speech recognition engine.
Next time, we will explain the UI and UX for speech recognition.
Most Viewed Articles
-
A quick explanation of how speech recognition works!
-
Comparing the speech recognition rates of OpenAI's Whisper and AmiVoice for "conference" audio
-
How to use the AmiVoice API free coupon
New Articles
-
Organizing the AmiVoice API manual for AI generation - Providing Markdown and llms.txt files -
-
How to Choose a Speech Recognition API: 4 Comparison Points to Avoid Mistakes
-
Things to know before implementation: the accuracy of Japanese speech recognition
Category List
- Tech (1)
- Introduction to Speech Recognition (16)
- How to Improve Speech Recognition Accuracy (12)
- Tried Building It (27)
- How to Use AmiVoice API (29)
- Comparison and Verification (8)
- Others (10)
Archive