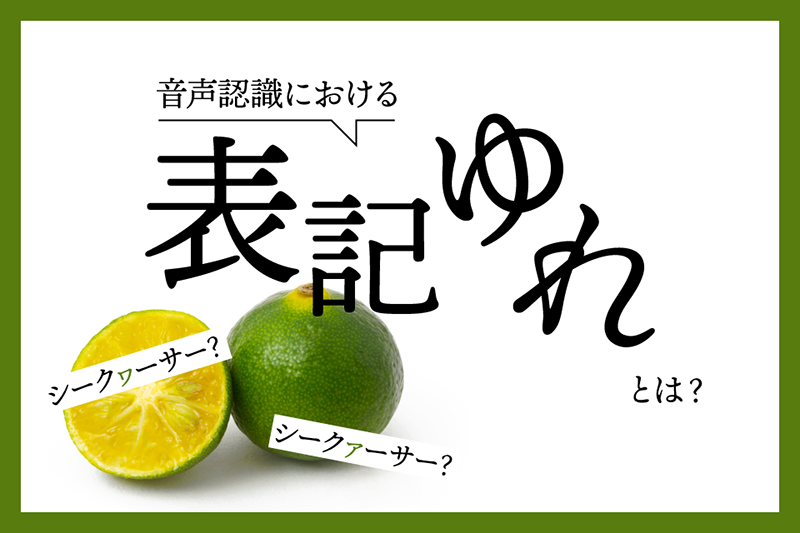
What is "notation variation" in speech recognition?
 Takashi Okura
Hello everyone!
In an article I previously wrote titled "Why Can't Speech Recognition Accuracy Reach 100%?", I introduced "notation variations" as one of the contributing factors.
AmiVoice Cloud Platform-Tech Blog
In this article, we will delve a little deeper into this "notation variation." In addition to explaining what notation variation is,
- In what situations does the notation variation become a problem?
- How much notation variation occurs in speech recognition?
I would also like to explain these points.
Table of contents
- What is notation variation?
- When notation variations are a problem
- To what extent does notation variation occur?
- Final thoughts
What is notation variation?
"Notation variation" refers to the fact that words have the same sound and meaning but are written differently. For example, there are the following patterns:
| Pattern | Example |
|---|---|
| Kanji and Kana | 様々 / さまざま |
| Differences in okurigana | 引っ越し / 引越し / 引越 |
| Differences in kana spelling | バイオリン / ヴァイオリン |
| Alphabet and Kana | AmiVoice / アミボイス |
| Kanji and Arabic numerals | 二千円 / 2000円 |
Furthermore, Mr. Ando, who frequently appears in this blog, says that "シークヮーサー" is the "ultimate example of notation variation". Just off the top of my head, there are:
- シークヮーサー
- シークワーサー
- シークァーサー
- シイクワシャー
- ...
and so on. *1
When notation variations are a problem
In what cases does this "notation variation" cause problems? Here are three examples of problems.
Text search becomes difficult
The most common method of utilizing speech recognition results is "converting speech to text and storing it," such as for meeting minutes. One of the advantages of this text conversion is that "the content can be searched later".
Let's consider the case where there is variation in the text of the recognition results. For example, if you search for "AmiVoice" in the text, "アミボイス" will not appear in the search results if the condition is an exact match.
Using OR searches or regular expressions, you can deal with slight variations in spelling, but when it comes to something like "シークヮーサー", it becomes difficult to cover all patterns. *2
May affect speech recognition rate
As I mentioned in a previous article, speech recognition rates are basically calculated on a character-by-character basis, so variations in spelling can sometimes be counted as errors.
Regarding the "recognition accuracy (recognition rate)" of speech recognition
AmiVoice Cloud Platform-Tech Blog
For example, if the correct text is "引越" but the recognition result is "引っ越し", the "っ" and "し" portions will be counted as insertion errors as is, resulting in an apparent decrease in speech recognition accuracy.
We will take a closer look at the extent to which notation variations occur and how they affect speech recognition rates in the next section.
Format mismatch
This is often the case with matters such as parliamentary minutes, where the format of numbers and other characters is strictly determined. For example, if the rule is that "numbers should be displayed in Arabic numerals," but the recognition result outputs "二千円", this is unacceptable even if it is a notation variation. Measures such as reviewing the training data and converting the Chinese numerals in the recognition results to Arabic numerals in post-processing are required.
To what extent does notation variation occur?
How much notation variation occurs in actual speech recognition?
Verification based on internal data, correcting notation variations such as "differences in okurigana" and "differences between kanji and hiragana *3" appears to improve recognition rates by approximately 1 to 2 percentage points *4. Of course, these values are for reference only, as they vary depending on the actual audio conditions and the engine used.
There were also cases like this:
We previously published an article comparing the speech recognition rates (recognition accuracy) of "general-purpose engines" and "domain-specific engines."
AmiVoice Cloud Platform-Tech Blog
The speech recognition rate shown in this article is
Recognition errors caused by variations in written form were corrected by revising the reference text.
Let me show them again, these are the values after correcting the notation variations.
| Engine | Speech recognition rate |
|---|---|
| Voice Input_General-purpose | 87.41 % |
| Voice Input_Electronic Medical Record | 97.61 % |
The table below also shows the speech recognition rates of these two engines before any notation variations were corrected.
| Engine | Speech recognition rate (Before modification → After modification) |
|---|---|
| Voice Input_General-purpose | 75.73 % → 87.41 % |
| Voice Input_Electronic Medical Record | 93.77 % → 97.61 % |
What do you think? The general-purpose engine shows a difference of more than 10 points in recognition rate due to the correction of notation variations, which may surprise some who find this a larger difference than expected. However, upon examining the recognition results, there were numerous notation variations related to differences in the test set format, such as "differences between full-width and half-width characters" and "differences between Arabic numerals and Chinese numerals". If the recognition rate of speech recognition does not meet your expectations, we recommend checking the recognition results and correct sentences to see if there are any notation variations, including such format differences.
Final thoughts
In this article, we have looked in detail at "notation variation" in speech recognition. As mentioned in the article "Why is speech recognition never 100% accurate?", there are many notation variations, and in many cases they cannot be converted mechanically. We hope that you can see that this is one of the difficult issues when dealing with speech recognition.
If you are a developer who has become interested in speech recognition technology or AmiVoice Cloud Platform after reading this article, please try https://acp.amivoice.com/. All engines are available free of charge for up to 60 minutes of audio per month.
Thank you for reading this far!
Person who wrote this article
-
Takashi Okura
He joined Advanced Media as a new graduate.
My current job mainly involves research and development to improve the accuracy of speech recognition.
His hobbies include traveling (mainly trains), reading (mainly novels), and board games.
*1: There was an easy-to-understand diagram on Wikipedia (シークヮーサー – Wikipedia). It would make for quite a calculation problem to determine how many different notation methods exist in total.
*2: Although this is not a result of speech recognition, when writing this article, it took me some time to search for the text chat where Mr. Ando had previously talked about "シークヮーサー". It didn't come up with "シークワーサー", but I finally found it by searching for "シーク". However, when searching for "シーク", results such as "シークレット" also appeared in the search results.
*3: Note that writing parts that can be written in kanji in hiragana is called "opening the kanji," and writing them in kanji as is is called "closing the kanji." For example, in this article, the "variation" part of "notation variation" is open kanji.
*4: This value does not refer to the "error improvement rate" explained in the previous article, but rather means that recognition with a 60% rate improves to approximately 61-62%, and recognition with an 80% rate improves to approximately 81-82%. For information on error improvement rate, please refer to this article → What is the difference between "error improvement rate" and "recognition accuracy (recognition rate)" in speech recognition? – AmiVoice Techblog
Most Viewed Articles
-
A quick explanation of how speech recognition works!
-
Comparing the speech recognition rates of OpenAI's Whisper and AmiVoice for "conference" audio
-
How to use the AmiVoice API free coupon
New Articles
-
Organizing the AmiVoice API manual for AI generation - Providing Markdown and llms.txt files -
-
How to Choose a Speech Recognition API: 4 Comparison Points to Avoid Mistakes
-
Things to know before implementation: the accuracy of Japanese speech recognition
Category List
- Tech (1)
- Introduction to Speech Recognition (16)
- How to Improve Speech Recognition Accuracy (12)
- Tried Building It (27)
- How to Use AmiVoice API (29)
- Comparison and Verification (8)
- Others (10)
Archive