AmiVoice API

What is AmiVoice API?

A speech to text API that converts speech to text. By sending audio to the API endpoint, you receive a transcribed text of the speech. Speech-enabled applications such as for conference transcriptions and voice dialogue systems can be created.

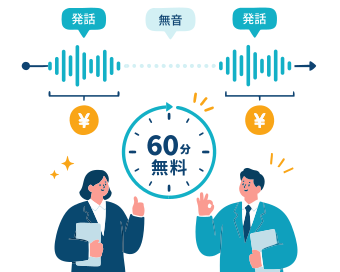
An illustration illustrating a system where only the spoken portion of the conversation is subject to billing.

60 minutes free per month; charges apply only to spoken time.

All engines offer 60 minutes of free use each month, providing high-quality speech recognition at a low price. Only the speech portion (spoken segments) is charged, and silent periods are not, allowing you to keep operating costs down.

An illustration representing technical support provided by specialist staff.

Free technical support from pre-implementation to operation.

Our expert staff provides free support, from pre-implementation consultations to setup and any questions you may have during operation. Even if you're new to using voice recognition, you can use it with confidence.

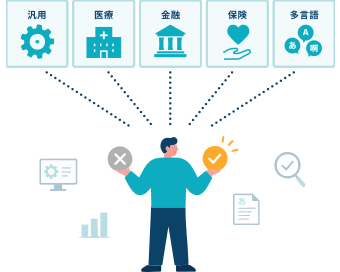
Illustrations representing speech recognition engines tailored to different industries and applications.

Specialized engines tailored to specific industries and applications

We offer speech recognition engines tailored to various industries and use cases, such as meetings, healthcare, and local government. They support specialized terminology and proper nouns, enabling highly accurate transcription suitable for your specific needs.

Illustrations of a map of Japan and voice recognition/security

High Japanese recognition accuracy and reliable domestic operation

This high level of recognition accuracy is possible precisely because, as a Japanese company, we have been conducting speech research specifically focused on the Japanese language for many years.
It generates natural-sounding Japanese text, taking into account even the nuances of spoken language and the use of punctuation.

Main functions

For detailed information on the features,Documentsto check more details.

  • Supports both real-time and batch text conversion.

    There are two main approaches: one that processes audio streams and short speeches quickly and converts them to text in real time, and another that processes large audio files in batches.

  • Always updated via auto-training

    The Conversation_General-purpose engine is constantly updated to the latest version by the Auto-Training System (ATS). It can also recognize new words that have only recently appeared.

  • Automatically add punctuation and question marks.

    Punctuation and question marks are automatically added to the recognition results, supporting the creation of more accurate and easily understandable spoken language.

  • Proper nouns can also be recognized through word registration.

    You can register words in the user dictionary, such as product names and proper nouns, depending on the usage scenario. This improves the recognition accuracy of specific words and phrases, such as company terminology and names.

  • Automatically remove fillers (hesitations/hesitations)

    Fillers such as "ah," "urm," and "hmm" are automatically deleted (you can also set them not to be deleted). This reduces the effort required to correct recognition results.

  • Hide inappropriate language

    You can use it with confidence because inappropriate terms (sexual language, discriminatory language, etc.) in official situations such as business settings will not be converted into text.

  • Display spoken form

    The speech recognition results include the estimated spoken forms derived from the speech. These can be used not only for display in applications for children, but also for data matching in downstream systems such as CRM and product databases.

  • Time stamp

    The speech recognition results are assigned a timestamp in milliseconds, with the beginning of the audio data being 0. This makes it possible to obtain the start and end times of each utterance.

  • Speaker Diarization

    This function identifies who spoke and when for audio containing multiple speakers. It identifies and labels speakers without prior training.

  • Sentiment analysis (optional)

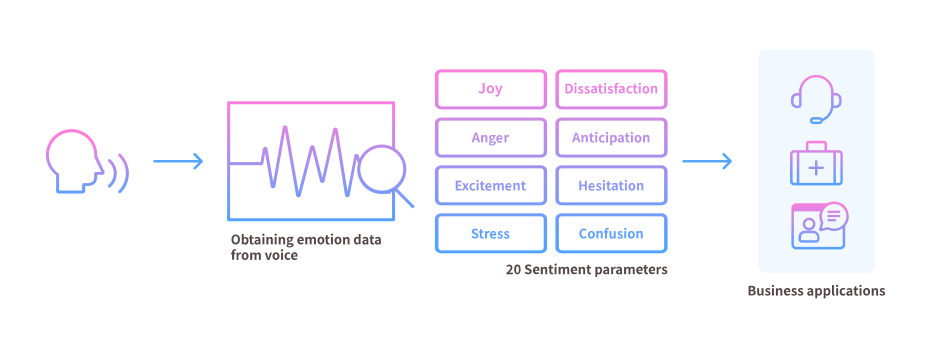
    It analyzes the speaker's emotions from their voice, outputting 20 parameters such as joy, anger, stress, dissatisfaction, and expectation. This enables detailed voice analysis.

Optional Features

Private connection (AWS PrivateLink)

This is a paid option for customers using the AWS environment, providing AWS PrivateLink connectivity to the "AmiVoice API". By creating a VPC endpoint in your Amazon VPC, you can use the speech recognition API from within the AWS network without going through the public internet. You do not need to prepare an internet gateway, NAT Gateway, or public IP address to connect to the speech recognition API. It can be used from systems that prohibit or restrict internet connectivity, simplifying network configuration and potentially reducing associated costs. Synchronous and Asynchronous APIs are separate options. If you use both, fees will be charged for each. If you wish to do so, please notify us through the inquiry form.

Sentiment analysisFree for up to 60 minutes per month

The system analyzes the speaker's emotions from the voice and outputs 20 parameters, such as joy, anger, stress, dissatisfaction, and expectation, approximately once every two seconds. It allows for more detailed voice analysis, such as being able to grasp the emotional ups and downs hidden behind the expression "thank you" for example. Sentiment analysis results can be used in a wide range of situations, including contact centers, marketing, human resources, and medicine. We provide ESAS technology. Based on the latest sentiment analysis engine provided by Israel's Nemesysco, it was developed by ES Japan through verification and research of 3 million audio sources in Japan. You can use it with the asynchronous HTTP speech recognition API. You can use it for free for up to 60 minutes per month, so please feel free to try it out.

AmiVoiceAPI sentiment analysis function (optional function)

AmiVoice API Case Studies

We also recommend these services:

Use API for Free